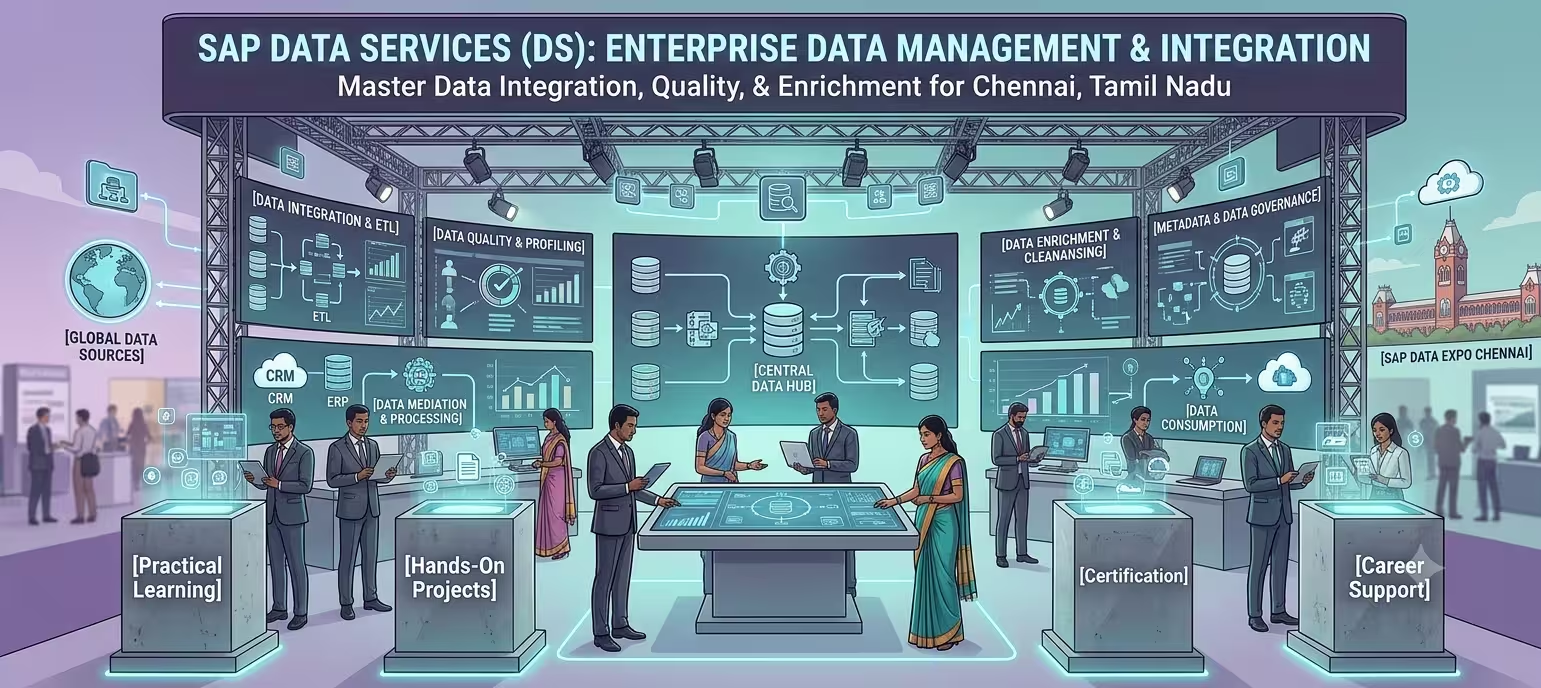
Course Objectives
1. Master Enterprise ETL Architecture
Learn to design and configure end-to-end Extract, Transform, and Load (ETL) data pipelines using the SAP Data Services Designer to connect disparate source and target systems efficiently.
2. Implement Advanced Data Quality & Cleansing
Acquire the skills to profile, parse, standardize, and de-duplicate messy corporate master data using built-in data quality transforms to ensure enterprise reporting runs on trusted information.
3. Orchestrate Complex Data Transformations
Master the configuration of advanced transformation logic, including history-preserving scenarios, delta processing, data pivoting, and custom validation rules for high-volume transactions.
4. Manage Large-Scale System Data Migrations
Gain hands-on expertise in staging, validating, and executing major system data cutovers—such as moving legacy non-SAP databases into modern SAP S/4HANA target systems safely
Popular Techniques Covered in This Course
1: Central & Local Repository Configuration
2: Datastore Management & Connection Setup
3: Graphical Data Flow & Workflow Engineering
4: Core Query Transform Optimization
5: Advanced Delta Capture (Change Data Capture - CDC)
6: Data Cleansing & Validation Rule Enforcement
7: Slowly Changing Dimensions (SCD Type 1 & Type 2)
8: Management Console Administration & Job Scheduling
9: Performance Tuning & Bulk Loading Optimization
10: System Exception Handling & Recovery Recovery Design
Get Hands-on Knowledge about Real-Time Projects
Project 1
Project 1: Heterogeneous Global Customer Data Consolidation Pipeline
Connect to an external legacy SQL customer database and separate flat CSV sales files, using the Query and Merge transforms to clean, join, and structure the data into a unified analytical target schema.
Project 2
Project 2: High-Volume History-Preserving Product Master Matrix (SCD Type 2)
Build an advanced product inventory pipeline using Table Comparison, Key Generation, and History Preserving transforms to automatically capture and log granular product price changes over time.
Project 3
Project 3: Automated Zero-Downtime Inventory Change Data Capture (CDC)
Design a smart, time-stamped warehouse delta engine that automatically detects and extracts only the inventory records modified within the last hour, updating target tracking systems in real time.
Project 4
Project 4: Enterprise-Grade Master Data Quality Cleansing & Validation Loop
Construct a rigorous validation gate that profiles incoming vendor addresses, standardizes mismatched text strings, strips out invalid null records, and programmatically isolates failures for administrator review.
Project 5
Project 5: Legacy ERP to SAP S/4HANA Migration Simulation
Plan and execute a realistic data cutover project, extracting operational legacy data pools, transforming them to fit strict SAP S/4HANA structural rules, and loading them smoothly via optimized staging tables.
Key Features
Edubrights offers SAP DS (Data Services) Training in virtual mode with expert trainers. Here are the key features,
40 Hours Course Duration
100% Job Oriented Training
Industry Expert Faculties
Free Demo Class Available
Completed 500+ Batches
Certification Guidance
Curriculum
Module 1: Introduction to SAP Data Services
- Overview of SAP Data Services (BODS)
- BODS use cases: ETL, data quality, data migration
- BODS architecture: Designer, Job Server, Repository
- Integration with SAP BW, HANA, and non-SAP sources
- BODS vs. SAP Data Intelligence
Module 2: BODS Architecture and Components
- Designer client and management console
- Job server and access server
- Local and central repositories
- Metadata management
- BODS deployment options
Module 3: Data Flows and Jobs
- Job, work flow, and data flow hierarchy
- Source and target datastores
- Data flow design and execution
- Conditional branching and scripts
- Job scheduling and automation
Module 4: Transforms and Functions
- Query transform and mapping
- Data integrator transforms
- Data quality transforms
- XML and flat file transforms
- Custom functions and scripts
Module 5: Source and Target Datastores
- Database datastores: Oracle, SQL Server, HANA
- SAP Application datastores: R/3, BW
- File formats: CSV, XML, Excel
- Web services and OData sources
- Adapter SDK for custom connectors
Module 6: Data Quality Management
- Data cleansing transforms
- Address validation
- Data standardization rules
- Duplicate record detection
- Data quality dashboards
Module 7: CDC (Change Data Capture)
- CDC concepts and methods
- Log-based CDC configuration
- Timestamp-based CDC
- Real-time data replication
- CDC monitoring and error handling
Module 8: SAP Data Migration with BODS
- Migration methodology with BODS
- Source system analysis and profiling
- Mapping and transformation rules
- Reconciliation and validation
- Migration cutover support
Module 9: Performance Optimization
- Parallel data flows
- Pushdown optimization
- Caching strategies
- Partitioned loading
- Job performance monitoring
Module 10: Error Handling and Monitoring
- Error log analysis
- Recovery mechanisms
- Email notifications for failures
- Repository management and cleanup
- BODS administrator console
Module 11: BODS and SAP HANA Integration
- Loading data into SAP HANA
- HANA-specific optimizations
- Real-time replication to HANA
- Smart Data Access with BODS
- Migration to SAP Data Intelligence
Module 12: Real-Time Projects and Case Studies
- SAP ECC to S/4HANA data migration
- Data warehouse ETL implementation
- End-to-end BODS project
- Certification and interview preparation
Receive Training From Our Skilled and Effective Trainers
Experience in the Industry Gain knowledge from experts with hands-on SAP Data Services project experience in data migration and ETL implementations.
Backgrounds at the Top Prominent corporations such as HCL, TCS, Accenture, and Capgemini employ our SAP BODS trainers.
Clear & Effective Teaching Excellent communication and real-world examples simplify complex ETL design and data quality management.
Hands-On Learning Focus Students apply skills using live SAP BODS environments with real data migration and ETL projects.
Up-to-Date Knowledge Trainers stay current with SAP BODS, Data Intelligence migration paths, and latest data management best practices.
About Our Course Certification*
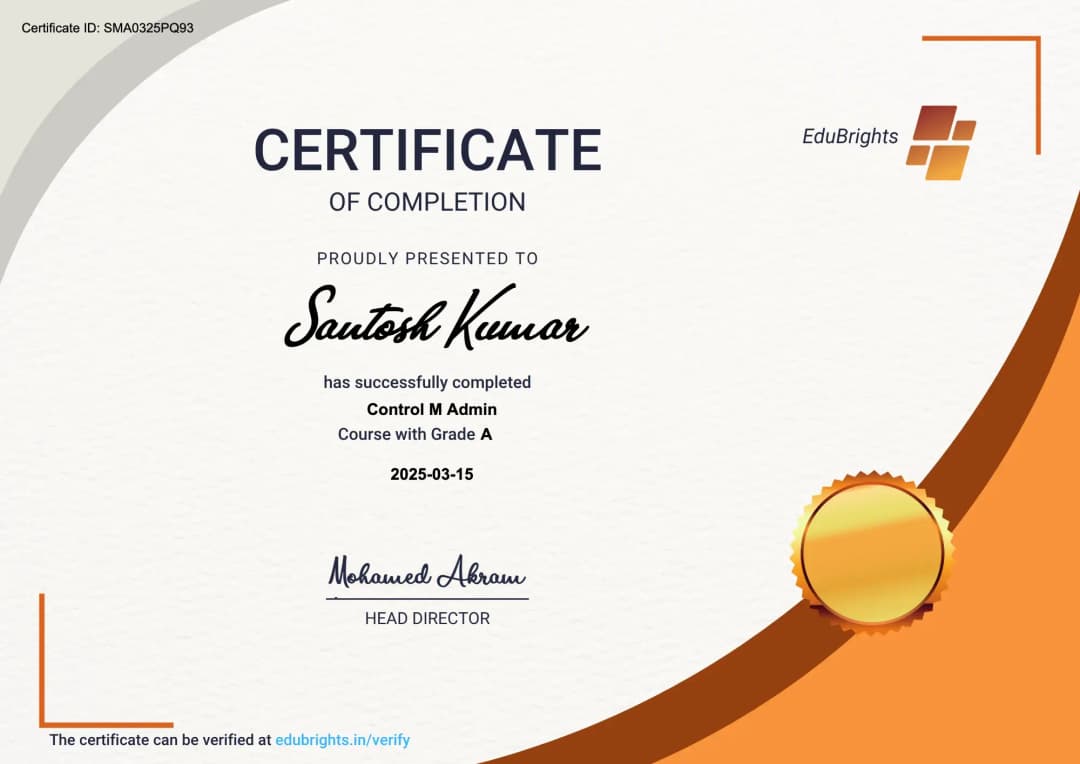
Our institution offers a recognized SAP DS (Data Services) certification that validates your ability to design and prototype professional user interfaces efficiently. This certification enhances your design portfolio and prepares you for collaborative projects in real-world environments. Gain practical skills through hands-on training and assessments.
Course FAQs
1. What is SAP Data Services (SAP DS)?
SAP Data Services is a data integration and data quality platform used to extract, transform, validate, and load data between different systems. It supports ETL processes, data migration, data consolidation, and enterprise reporting requirements.
2. What is SAP BODS, and how is it related to SAP Data Services?
SAP BusinessObjects Data Services (BODS) is the commonly used name for SAP Data Services. It provides tools for designing data integration jobs, transforming source data, improving data quality, and loading information into target systems.
3. What are the main components of SAP Data Services architecture?
The main components include Designer, repositories, Job Server, Management Console, and Access Server for applicable real-time scenarios. These components support development, metadata storage, job execution, administration, scheduling, and real-time data processing.
4. What is SAP Data Services Designer?
Designer is the development interface used to create projects, jobs, workflows, data flows, and transformation logic. Developers use it to connect source and target objects, configure data processing, validate jobs, and test ETL workflows.
5. What is a repository in SAP Data Services?
A repository stores metadata about development objects, such as jobs, workflows, data flows, datastores, and transformations. A local repository supports individual development, while a central repository can support shared development and version-control processes.
6. What is the role of the SAP Data Services Job Server?
The Job Server executes data integration jobs designed in Designer. It processes data flows, runs transformations, manages job execution, and supports scheduled batch processing.
7. What is the SAP Data Services Management Console?
The Management Console is a web-based administration interface used for monitoring and managing Data Services operations. Depending on the configuration, it supports job scheduling, execution monitoring, repository administration, and operational troubleshooting.
8. What is a project in SAP Data Services?
A project is a development object used to organize related jobs and their supporting objects. It helps developers manage ETL tasks logically and maintain a structured development environment.
9. What is a job in SAP Data Services?
A job is an executable object that coordinates data processing activities. It can contain workflows, data flows, scripts, and other steps that run sequentially or in parallel according to the configured execution logic.
10. What is the difference between a job, workflow, and data flow?
A job is the executable unit, a workflow organizes and controls the sequence of activities, and a data flow defines how data moves from sources through transformations to targets. Together, these objects form the core structure of an SAP Data Services ETL solution.
11. What is a datastore in SAP Data Services?
A datastore contains connection information for a database, SAP application, or other supported data source. It also enables developers to import source and target metadata for use in data flows.
12. How do you configure a datastore in SAP Data Services?
Datastore configuration involves selecting the connection type, entering the required connection details, and validating connectivity. After establishing the connection, developers can import metadata and use the available objects in ETL jobs.
13. How does SAP Data Services connect to SAP applications?
SAP Data Services can connect to supported SAP applications through application datastores and appropriate interfaces. Depending on the source and extraction scenario, connectivity may use RFC, ODP, IDoc, or other supported methods. citeturn995395search5
14. How does SAP Data Services connect to non-SAP databases?
It can connect to supported databases using database datastores and the appropriate drivers or connection settings. Once connected, developers can import table metadata and use the data as sources or targets in ETL processes.
15. What are source and target objects in SAP Data Services?
A source object provides the data to be processed, while a target object receives the transformed results. Sources and targets may include database tables, flat files, SAP application objects, or other supported data structures.
16. What is a data flow in SAP Data Services?
A data flow defines the extraction, transformation, and loading logic for a specific data-processing task. It connects source objects, transformation objects, and target objects to determine how records are processed and delivered. citeturn995395search2
17. What is the Query transform in SAP Data Services?
The Query transform is used to filter, join, map, and manipulate data within a data flow. It supports operations such as column mapping, expressions, conditional filtering, and other SQL-like data-processing logic.
18. How are joins performed in SAP Data Services?
Joins combine records from multiple sources using matching keys or defined join conditions. Developers can configure the appropriate join type and verify that the resulting data meets the business requirements.
19. What is the difference between filtering and mapping in a data flow?
Filtering determines which records should continue through the data flow based on specified conditions. Mapping assigns or transforms source fields into target fields, including applying expressions to change values or formats.
20. What are data transformation functions in SAP Data Services?
Transformation functions modify data to meet target-system requirements. They can perform calculations, string manipulation, date conversion, conditional logic, type conversion, and other operations during ETL processing.
21. What is the Case transform used for?
The Case transform applies conditional logic to determine how input records should be processed. It can assign different output values or routes based on business rules and specified conditions.
22. What is the Lookup function in SAP Data Services?
Lookup functionality retrieves related information from a reference dataset based on specified matching conditions. It is useful for enriching source records with descriptions, classifications, codes, or other required attributes.
23. What are variables and parameters in SAP Data Services?
Variables store values that can be used during job execution, while parameters allow developers to supply configurable inputs to jobs and related objects. They improve reusability by allowing the same ETL logic to run with different dates, file names, filters, or environment settings.
24. What are scripts used for in SAP Data Services?
Scripts execute expressions and logic that support job or workflow processing. They can initialize variables, evaluate conditions, prepare execution settings, and control subsequent steps within a data integration process.
25. What is a flat-file format in SAP Data Services?
A flat-file format defines the structure of a text-based source or target file. It can specify delimiters, column positions, data types, header information, and other settings required to read or write files correctly.
26. How does SAP Data Services process CSV files?
Developers configure a flat-file format that matches the CSV structure, including its delimiter, columns, and header settings. The file can then be used as a source or target in a data flow for cleansing, transformation, and loading.
27. What is data quality management in SAP Data Services?
Data quality management identifies and addresses inaccurate, incomplete, inconsistent, or duplicate information. SAP Data Services provides data quality capabilities and supported transformations that help standardize and validate data before it reaches target systems.
28. How can duplicate records be identified in SAP Data Services?
Duplicate records can be identified using business keys, matching conditions, grouping logic, and supported data quality capabilities. The appropriate approach depends on whether duplicates are exact copies or records that represent the same real-world entity despite differences in formatting.
29. How can missing or invalid data be handled in an ETL process?
Developers can apply validation rules, conditional logic, default values, and exception-handling procedures to manage missing or invalid records. Records that fail validation can be corrected, rejected, or directed to an error-handling process according to business requirements.
30. What is data cleansing in SAP Data Services?
Data cleansing improves the accuracy, consistency, and usability of information before loading it into a target system. Common activities include standardizing formats, correcting invalid values, handling missing fields, resolving duplicates, and validating business rules.
31. What is data migration using SAP Data Services?
Data migration uses ETL jobs to extract data from legacy or source systems, transform it into the required structure, and load it into a target application. Data Services can support migration projects through reusable jobs, mapping logic, validation, reconciliation, and error handling.
32. How is SAP Data Services used with SAP BW?
SAP Data Services can extract and transform data from supported sources and provide it to SAP Business Warehouse through an appropriate integration design. This supports data preparation, consolidation, and loading for reporting and analytics.
33. How does SAP Data Services integrate with SAP HANA?
SAP Data Services can use supported connectivity to read from and load data into SAP HANA environments. It can prepare source data, apply transformation rules, and populate target structures used for analytics or application processing.
34. What is an ABAP data flow in SAP Data Services?
An ABAP data flow is used for supported SAP application extraction scenarios where Data Services generates ABAP logic for execution in the SAP system. It can help perform source-side processing before the extracted results are returned to Data Services for further transformation. citeturn995395search10
35. What is the difference between batch jobs and real-time jobs?
Batch jobs process data in scheduled or manually initiated runs, making them suitable for periodic integration and migration tasks. Real-time jobs respond to supported incoming requests or messages and are used when data must be processed in response to an event or request.
36. How are jobs scheduled in SAP Data Services?
Batch jobs can be scheduled through the Management Console or a supported external scheduler. Scheduling configuration defines when a job runs, while monitoring helps administrators review execution status and identify failed runs. citeturn995395search3
37. What is conditional branching in SAP Data Services?
Conditional branching allows a job or workflow to follow different execution paths depending on defined conditions. It is useful when subsequent processing depends on validation results, file availability, job status, or other business rules.
38. How can parallel processing improve ETL performance?
Parallel processing allows independent job steps or data-processing activities to execute at the same time where the design and system resources permit. Developers should assess dependencies, source-system capacity, target-system capacity, and available resources before increasing parallel execution.
39. What is incremental data loading in SAP Data Services?
Incremental loading transfers new or changed records instead of reprocessing the entire dataset every time. It typically relies on a suitable change indicator, timestamp, key comparison, or source-supported change data capture mechanism.
40. How is error handling implemented in SAP Data Services?
Error handling can use validation rules, conditional logic, error outputs, execution settings, and job-level monitoring. A well-designed process records failed records and execution details so that errors can be investigated and corrected without losing control of the data load.
41. How do you debug a failed SAP Data Services job?
Start by reviewing the job execution log and identifying the step or data flow that failed. Then check datastore connectivity, metadata, transformation expressions, source data, permissions, and target constraints before rerunning the corrected job.
42. What is job validation in SAP Data Services?
Job validation checks whether the designed objects and their configurations are valid before execution. It can help identify configuration problems, missing objects, or syntax issues that could prevent a job from running successfully.
43. How can ETL data be reconciled after loading?
Reconciliation compares source and target results using record counts, key totals, financial totals, and other relevant business checks. It helps confirm that the expected data was transferred accurately and that transformations did not introduce unintended differences.
44. What are metadata management and data lineage in SAP Data Services?
Metadata management maintains information about data structures, objects, and their relationships within integration projects. Data lineage helps teams understand how source data moves through transformations into target structures, supporting impact analysis and troubleshooting.
45. What is the role of version control in SAP Data Services development?
Version control helps teams track changes to development objects and coordinate work across developers and environments. Repository and deployment practices should be designed to support controlled promotion, change review, and recovery when an update causes problems.
46. How are SAP Data Services jobs moved between development, testing, and production?
Jobs and related objects are promoted using supported export, import, repository, and deployment procedures appropriate to the landscape. Connection details, environment-specific parameters, permissions, and dependencies should be checked before executing the deployed jobs.
47. What is the difference between SAP Data Services and SAP Data Intelligence?
SAP Data Services focuses on data integration, ETL, data quality, and related batch or real-time integration scenarios. SAP Data Intelligence is designed for broader data orchestration and data pipeline management across complex data landscapes, including advanced data-processing scenarios.
48. What practical projects can be included in SAP Data Services training in Chennai?
Suitable hands-on projects include Customer Master Data Migration, Multi-Source ETL Integration, Data Cleansing and Duplicate Detection, SAP HANA Data Loading, and Automated Data Reconciliation. These projects help learners practice source connectivity, transformations, validation, scheduling, and troubleshooting.
49. What technical skills can learners develop through SAP Data Services training in Chennai?
Learners can develop skills in SAP Data Services architecture, Designer, repositories, datastores, jobs, workflows, data flows, Query transforms, scripts, parameters, flat-file processing, data quality, ETL development, SAP connectivity, data migration, scheduling, debugging, and reconciliation. Practical exercises help connect these technical concepts to common data integration requirements.
50. How does SAP Data Services training prepare learners for implementation projects?
Training can help learners understand how to design ETL workflows, connect source and target systems, transform and validate data, monitor job execution, and troubleshoot processing failures. Applying these skills in project-based exercises provides a foundation for contributing to data integration, migration, and data quality implementation work.
Get Training Quote for Free
Testimonials
Hear What Our Students Say
"Transform your life through Education, hear it from our Alumni"

6 LPA
Fathima
Student
Software Engineer
"Transform your life through Education, hear it from our Alumni"
8 LPA
Rahul
Student
Data Scientist
"Transform your life through Education, hear it from our Alumni"
8 LPA
Siddharth
NIELSON IQ
Data Analyst